Comparisons
Data Governance
Enterprise AI
Factory vs Devin for private AI development
October 1, 2026 - 7 minute read
Comparisons
Data Governance
Enterprise AI
October 1, 2026 - 7 minute read
Sierra, OpenCode, Hermes, Amp, Oh My Pi (OMP), Pi, OpenAI, and Anthropic raise different data-handling questions. Customer conversations, repository contents, saved agent memory, and model requests need different controls. A Factory vs Devin privacy decision starts by following each copy of engineering data across the proposed system.
Factory's Droid and Cognition's Devin should be evaluated against the same data classifications. As of October 1, 2026, both vendors document private deployment options. Local execution, no-training commitments, and dedicated infrastructure each answer a different part of the privacy review.
Sierra focuses on customer experience agents. Its evaluation should start with the customer records and business systems involved in that workflow. Those data categories differ from a coding harness reading source files, even when the same enterprise procures both.
OpenCode documents approved-provider restrictions and recommends disabling share pages for organizations that need to prevent that export path. A reviewer can test provider selection and sharing separately. Neither control alone proves that every extension, tool, or command stays inside an approved boundary.
Pi keeps its core minimal and adds capabilities through extensions, skills, and packages. Review the deployed package set alongside the model endpoint. Oh My Pi includes language-server and debugging tools alongside its coding workflow. Those integrations expand the systems a privacy review needs to inspect, without by themselves establishing a hosting or retention guarantee.
Hermes memory documentation describes persistent memory and skill updates from experience. Include those saved artifacts in deletion and access reviews. Amp's security reference covers infrastructure, retention, encryption, and model-training policies, so assess the configured service and its contract rather than inferring privacy from a local interface.
OpenAI's Codex approval and security documentation addresses sandboxing and network controls. Check the selected mode and approved destinations. Anthropic's enterprise deployment documentation describes Claude Code provider and gateway configuration. Existing cloud-provider agreements can affect that choice, but they still need to cover the actual inference path.
Factory and Cognition then become a more specific infrastructure comparison. For Droid and Devin, request a component-level account of execution, inference, control-plane data, sessions, and telemetry. An open or configurable harness and a managed platform should face the same requirement to identify the destinations their deployed configuration uses.
Factory's data-flow documentation distinguishes local filesystem activity, model requests, and telemetry. Droid's agent loop runs on the machine where Droid is installed. File contents included in prompts or tool context can still leave that machine through the configured inference path.
This gives a security review a concrete starting point. Identify the runtime, the model destination, and the systems receiving operational data. Then account for session synchronization and any connected tools. Running Droid on an internal server alone does not establish that every other part of the workflow remains internal.
Cognition's enterprise overview states that customer data is stored within the customer's tenant for dedicated or on-prem deployments. It also describes retaining Devin data for the customer relationship unless specified otherwise. That is relevant deployment and retention information, not a reason to assume Devin always stores enterprise data in shared infrastructure.
For either vendor, turn the proposed architecture into a data inventory. Include repository contents, prompts, tool output, session records, authentication information, and support artifacts. Record the recipient and retention policy for each category. Distinguish stored data from data that passes through an inference service.
Factory's useful property here is the documented separation between the runtime and the model or gateway it uses. An organization with an approved inference service can evaluate that service as an explicit part of its Droid deployment. The service's privacy commitments still need independent review.
Factory documents cloud-managed, hybrid, and fully airgapped deployment patterns. These patterns differ in their runtime dependencies and data boundaries. A hybrid deployment can combine customer infrastructure with selected cloud features, while the fully airgapped pattern has no Factory cloud dependency at runtime.
The same documentation describes an Enterprise EU deployment with separate regional backend, session storage, and inference endpoints. It also identifies an important exception: organization pointers, user profiles, and billing data remain in the global US deployment. A requirement that every category of data remain in Europe needs to account for that exception.
Devin's enterprise deployment documentation distinguishes Enterprise Cloud from Customer Dedicated Deployment. Compare the proposed implementation, including customer and vendor responsibilities, rather than translating a deployment label into an assumed guarantee.
Cognition's CLI reference includes devin airgap doctor for checking airgapped configuration and model endpoint connectivity. Include that CLI path alongside the hosted and dedicated options. Require the applicable deployment guide, license terms, model requirements, and feature limitations for the exact Devin configuration under consideration.
Factory's airgap runbook is explicit about Droid's behavior. A dedicated Enterprise build skips Factory sign-in, cloud session sync, crash reporting, update checks, and Factory-bound telemetry. It uses the custom model endpoints and policy sources configured inside the environment.
For that dedicated build, Factory-managed models and Factory Router are unavailable in Airgap Mode. Cloud-dependent capabilities such as session sharing, Slack integration, and hosted analytics are unavailable too. Internal models, artifacts, Git access, and collectors become part of the customer's operating responsibility.
Factory also distinguishes offline behavior from enforcement. Airgap Mode skips Factory-bound work, but network isolation comes from the customer's infrastructure and sandbox policy. This is a useful operational contract for a buyer who wants to validate the boundary rather than rely on a product label.
Factory's September 23, 2026 Router report describes a different scope from the dedicated Airgap Mode runbook. Factory Private, in private preview, supports routing with internally hosted model endpoints, including air-gapped deployments. The report says model selection and task execution stay within the organization's environment. Confirm preview access and the supplied build rather than assuming this capability applies to every airgap installation.
The same report provides measured cost data for Factory-managed inference. Weekly aggregate savings rose from 42% in late June to 63% in the week ending September 13, 2026. The baseline prices the same workload at published frontier-model rates.
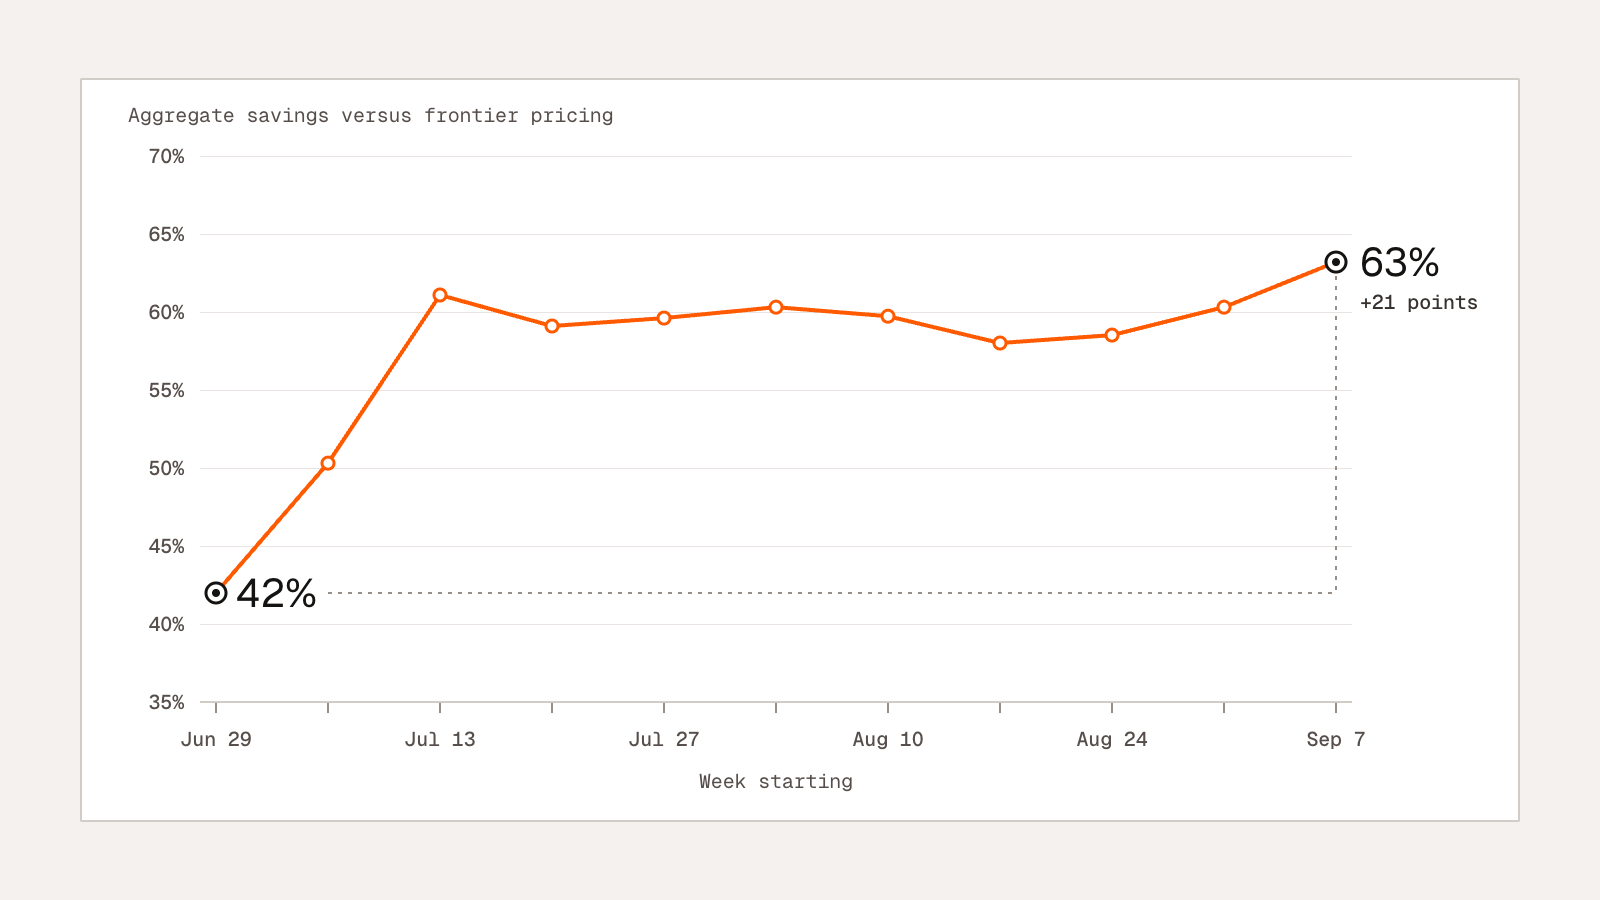 Weekly aggregate savings compared with frontier pricing, June 29 to September 13, 2026. Savings axis: 35–70%.
The 63% figure is an aggregate for that reporting window. It does not measure savings against Devin, Amp, or another harness, and it does not establish savings for a customer's private model fleet. Factory explicitly says Private savings depend on configured models and the prices the organization pays.
For a private pilot, record selection calls as well as execution calls. Reconcile billed usage with the approved endpoint inventory, then calculate cost per accepted task. A lower inference bill is useful only if the deployed configuration also satisfies the required data boundary and produces an acceptable result.
Cognition's security documentation describes a training opt-out that also enables zero data retention with its model providers. Confirm the plan, applicable defaults, and contract. A model-provider retention commitment does not automatically delete application sessions, source-control artifacts, or customer-managed logs.
Factory's managed settings expose separate controls for cloud session synchronization, cloud session retention, and model access. The documented session-retention setting accepts 14 to 365 days. That setting governs cloud sessions, not every copy of data throughout a customer's environment.
Model governance is another separate decision. A centrally selected endpoint can make it easier to establish which provider agreement applies. Factory documents allowed custom-model base URLs and controls over whether users can add their own custom models. A personal API key should not silently introduce a destination that has not passed review.
Factory's BYOK documentation states that custom model credentials stay local and that custom models are available in the Droid CLI and desktop app. They do not appear in the hosted web or mobile platforms. That surface distinction matters when a proposed workflow depends on an internal gateway.
Ask both vendors for a written treatment of deletion, backups, support access, and any contract-specific exceptions. Keep those answers attached to the selected plan and architecture. No-training, model-provider zero retention, application retention, and network isolation should remain separate entries in the approval record.
Factory's telemetry privacy controls distinguish metrics from optional message-content spans. Content export is off by default and requires a customer-configured collector. Factory's collector does not receive spans.
That distinction is narrower than saying no content can ever reach any Factory service. Cloud session synchronization has its own control and purpose. A telemetry setting should not be used as evidence about a separate application data flow.
Factory documents aggregate telemetry mode, which removes specified user identifiers and suppresses message content. Some attributes, including session and repository context, remain. Review the exported fields against the organization's privacy policy rather than assuming that the word “aggregate” makes every datapoint anonymous.
There is a second important qualification. If a customer enables message-content export, the documentation says that the content is raw, without PII scrubbing or secret detection. That collector needs appropriate access control and retention. A customer-owned destination can still expose sensitive data if it is configured carelessly.
For a private deployment, test telemetry with synthetic prompts and harmless tool output. Inspect the actual records at the collector. Record the fields and destinations that appear, and confirm what happens when content export is disabled.
A useful pilot begins with a representative repository containing no production secrets. Restrict egress to the approved destinations, run a bounded engineering task, and inspect the network and storage evidence. Exercise a denied endpoint as well as a successful request.
For an airgapped evaluation, repeat the test without public connectivity and through a restart. Confirm that model access, policy distribution, artifact installation, and the permitted engineering workflow still operate. Review which cloud features have deliberately been removed from the design.
Factory deserves preference when its explicit runtime, model, telemetry, and offline controls match the organization's operating requirements. Cognition's dedicated deployments and airgapped CLI capabilities should remain in the comparison. The choice should rest on the boundary the team can demonstrate, including its limitations, rather than a blanket claim that one vendor keeps everything private by default.
Review a Factory deployment against your required data boundary.
Start building

