Factory Private
Data Governance
AI code data residency beyond the repository
September 18, 2026 - 2 minute read
Factory Private
Data Governance
September 18, 2026 - 2 minute read
AI code data residency extends beyond the Git server. A development task can read a local file, send part of it to a model, and preserve the result in a separate log. The repository's location answers only one part of that path.
Security reviewers need to know what leaves the execution machine, where it is processed, and what persists. Treat source, prompts, test output, and diagnostic records according to their actual contents.
Factory's data-flow documentation states that Droid reads and edits files locally without uploading or indexing a static repository copy into a remote datastore. File contents used as inference context follow the configured model path.
The published comparison below separates the cloud-managed, hybrid, and airgapped boundaries.
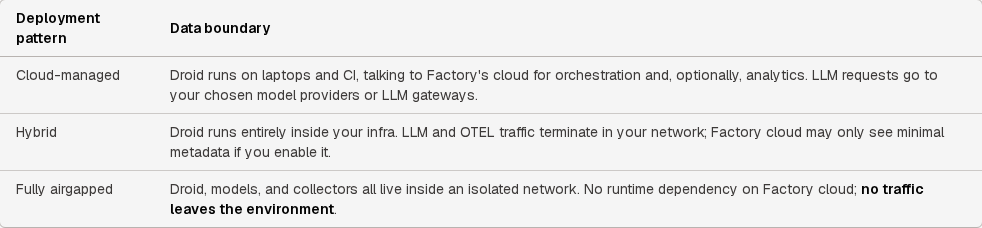
Screenshot of the linked data-flow documentation, captured September 18, 2026.
Inspect the service behind a gateway. A private address can forward to an external provider. Record its region, operator, retention conditions, and fallback route. Test the route from each execution environment, because workstation and runner proxies may differ.
Model choice and control-plane placement are separate decisions. The sovereign software development whitepaper distinguishes Factory-hosted Managed session data from Private's customer-hosted arrangement.
Bringing a model does not automatically relocate the control plane. Confirm session handling, administrative records, support diagnostics, and deletion procedures for the specific deployment.
The enterprise problem is illustrated by Nav's published case study. Gian Perrone, Nav's CTO, described the value of approved engineering context:
Factory provided us with a secure, controlled way to unify our engineering context without compromising our compliance requirements.
Source: Nav case study. This is Nav's account of its workflow, not evidence of a particular certification or a claim that Nav uses the current Factory Private offering.
A hook, MCP service, or test command can send information beyond the model route. Inventory those destinations and the identities they use. Include failures, when a tool may return a verbose stack trace or create a diagnostic archive.
Factory's telemetry privacy controls distinguish identity granularity from message-content export. Content logging is off by default. When enabled, raw content goes only to the customer-configured collector, without automatic redaction.
That collector needs approval for the underlying data. Aggregate mode removes specified identifiers and prevents content export, but it retains some session and workload attributes. Review those retained fields before treating the dataset as anonymous.
Use synthetic data in a representative task. Observe destinations during file reads, inference, validation, and review. Compare the observed path with the approved diagram.
Record each destination's operator, purpose, retention policy, and enforcement point. Confirm that the responsible team can locate records and apply the agreed lifecycle. An undocumented retention assumption is weak audit evidence.
Repeat the test when adding a model route, collector, integration, or execution environment. These changes can alter data handling without changing the product name in the procurement record.
The outcome should let developers select an approved environment without making a fresh security judgment for every task. Reviewers should be able to explain the same environment's data paths from recorded evidence.
Start building